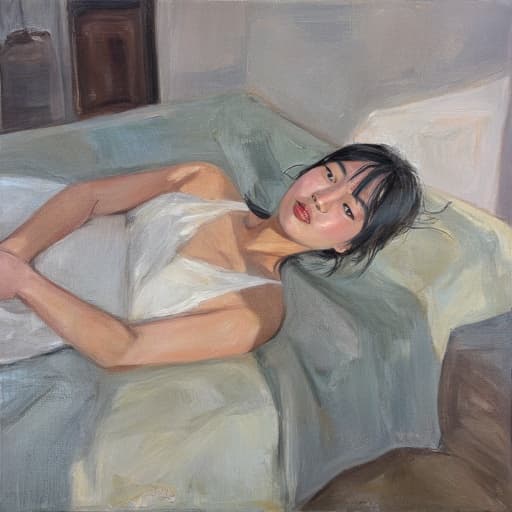
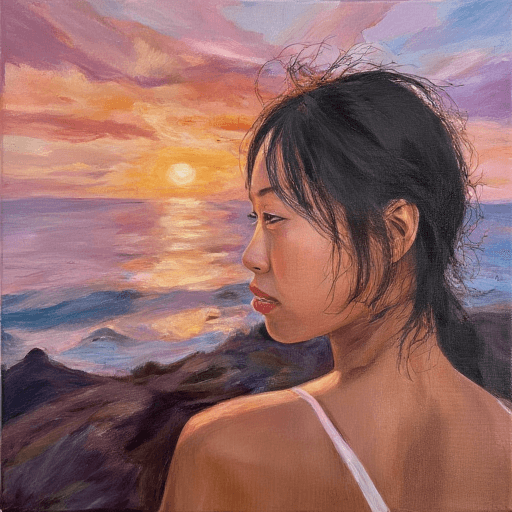
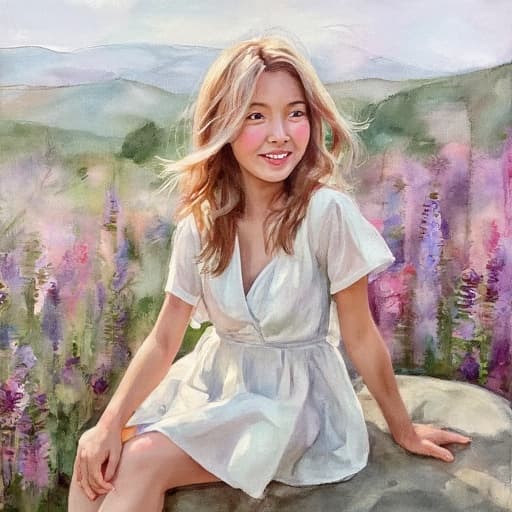
I trained a Flux 1.0 LoRA on 21 samples of my artwork from my recent portfolio, as a thought experiment on what parts of my work could be most easily understood and replicated by a machine. Each medium (oil, acrylic, watercolor, and colored pencil) was labeled as a substyle, and labels were generated using a chain of custom GPT-4o prompts. Here is an example of one of my works, and its label:
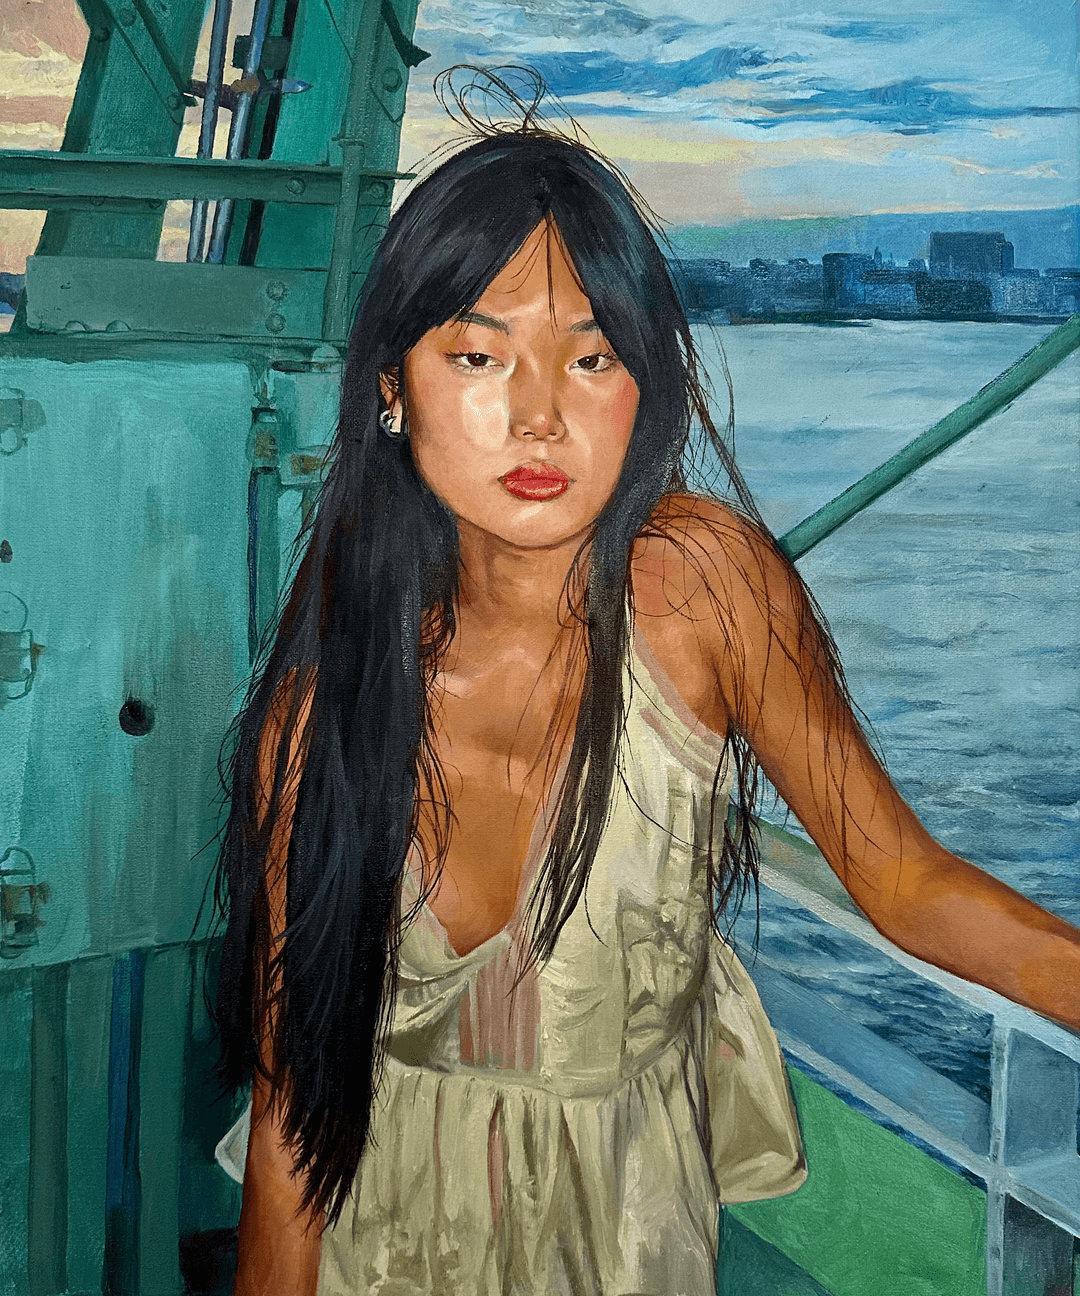
in the style of zsh-oil, 1girl, leaning on railing, oval face smooth tan skin, subtle asym mouth eyes, medium forehead, dark straight thick eyebrows, almond brown eyes medium lashes, gaze slightly past camera, straight medium nose rounded tip, full closed lips neutral, left ear silver stud earring, long straight black hair middle part stray strands, natural makeup soft blush muted pink lips, cream satin low v-neck spaghetti-strap dress loose fit, shoulders collarbones upper chest exposed, right arm extended back hand on railing, left arm bent on hip, slight forward lean torso turned slightly left, head upright slight tilt left, background, green metal structure left side vertical beams matte muted green with bolts, calm blue-teal water spans horizon gentle ripples, sunset sky upper band gradient blue to orange patchy clouds, distant dark cityscape silhouette along horizon, green-white metal guard railing runs behind subject, view from eye-level slight left front
I found the best stylistic consistency and sample quality at epoch 26, through lots of experimentation.
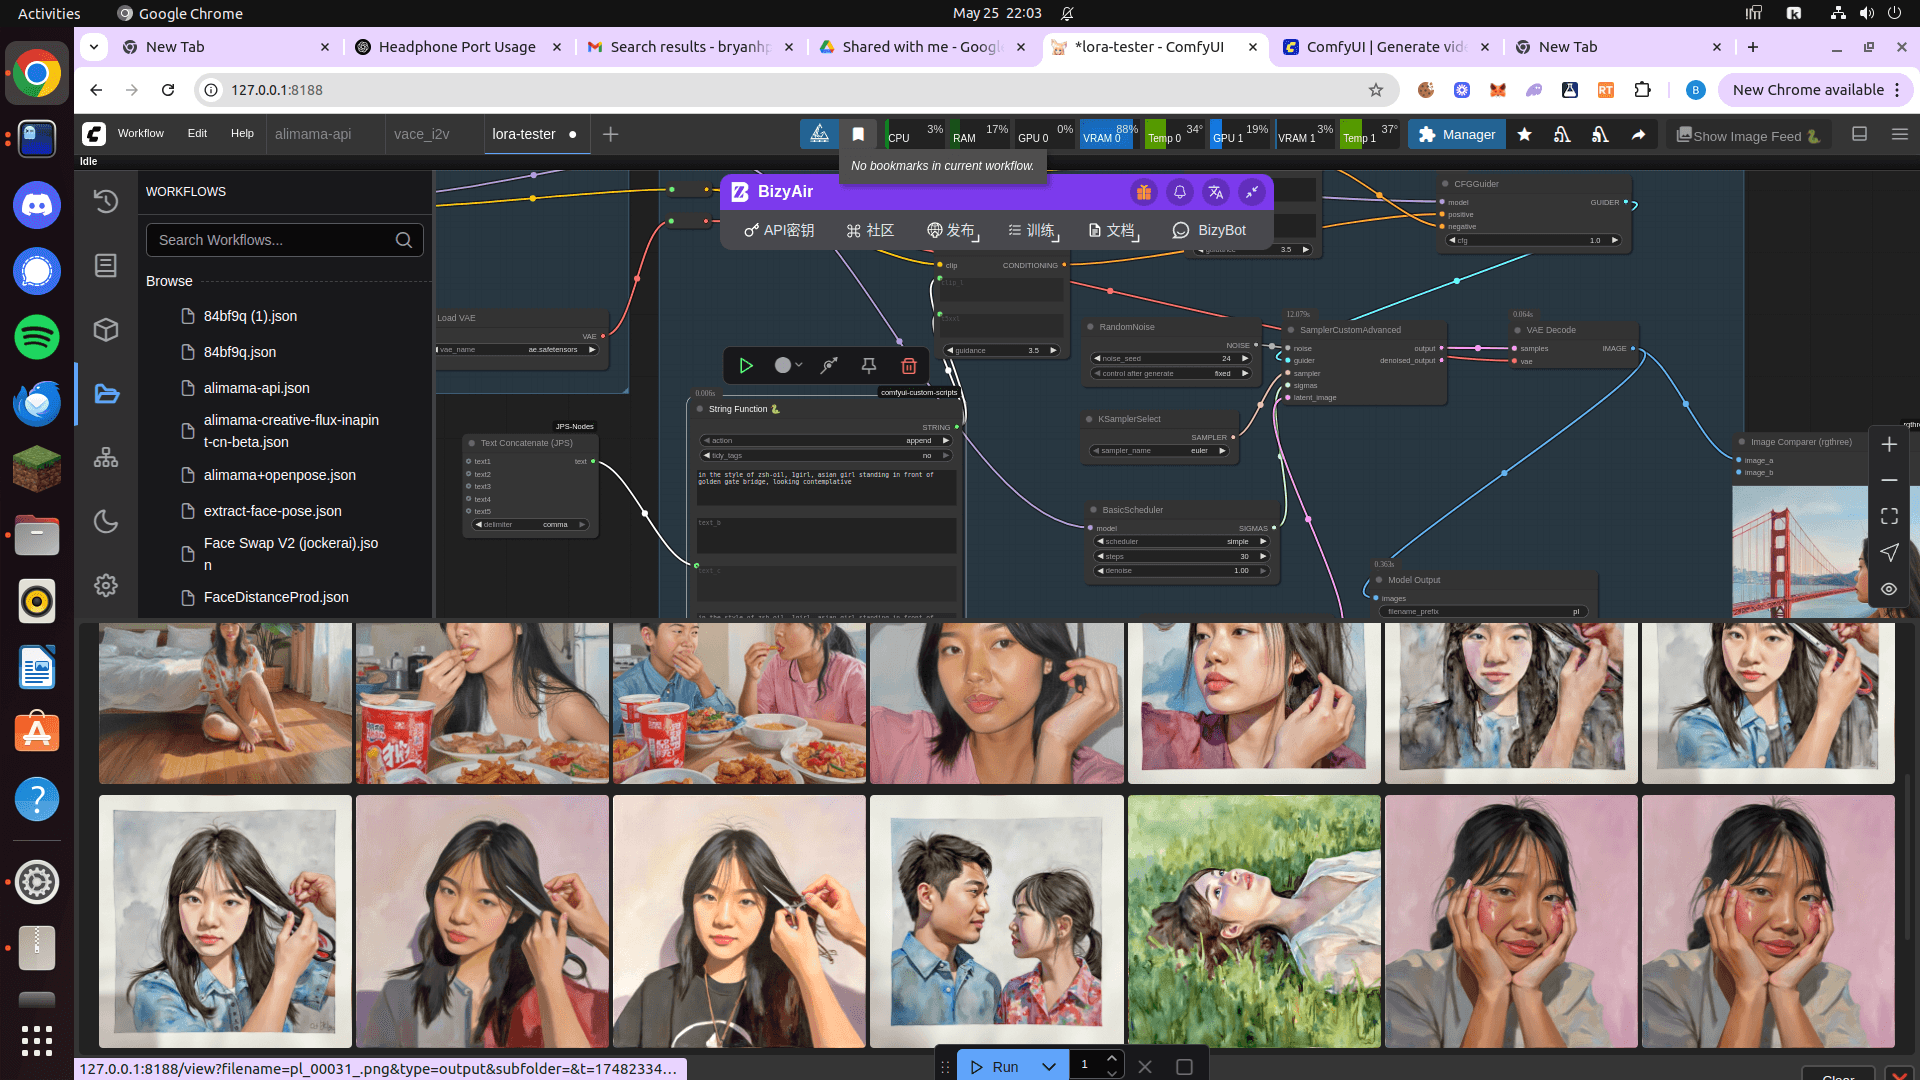
Notice the watercolor borders!
The LoRA was able to retain surprising formalistic elements, like the shading on the hair, the messy way I paint moving strands of hair, the sheen on the canvas, the general tones and hues of the shadows (especially on the skin), and the border from artist's tape on my watercolor portraits. Also all the asian girls look vaguely like my cousin, who appears many times in the works I trained on.
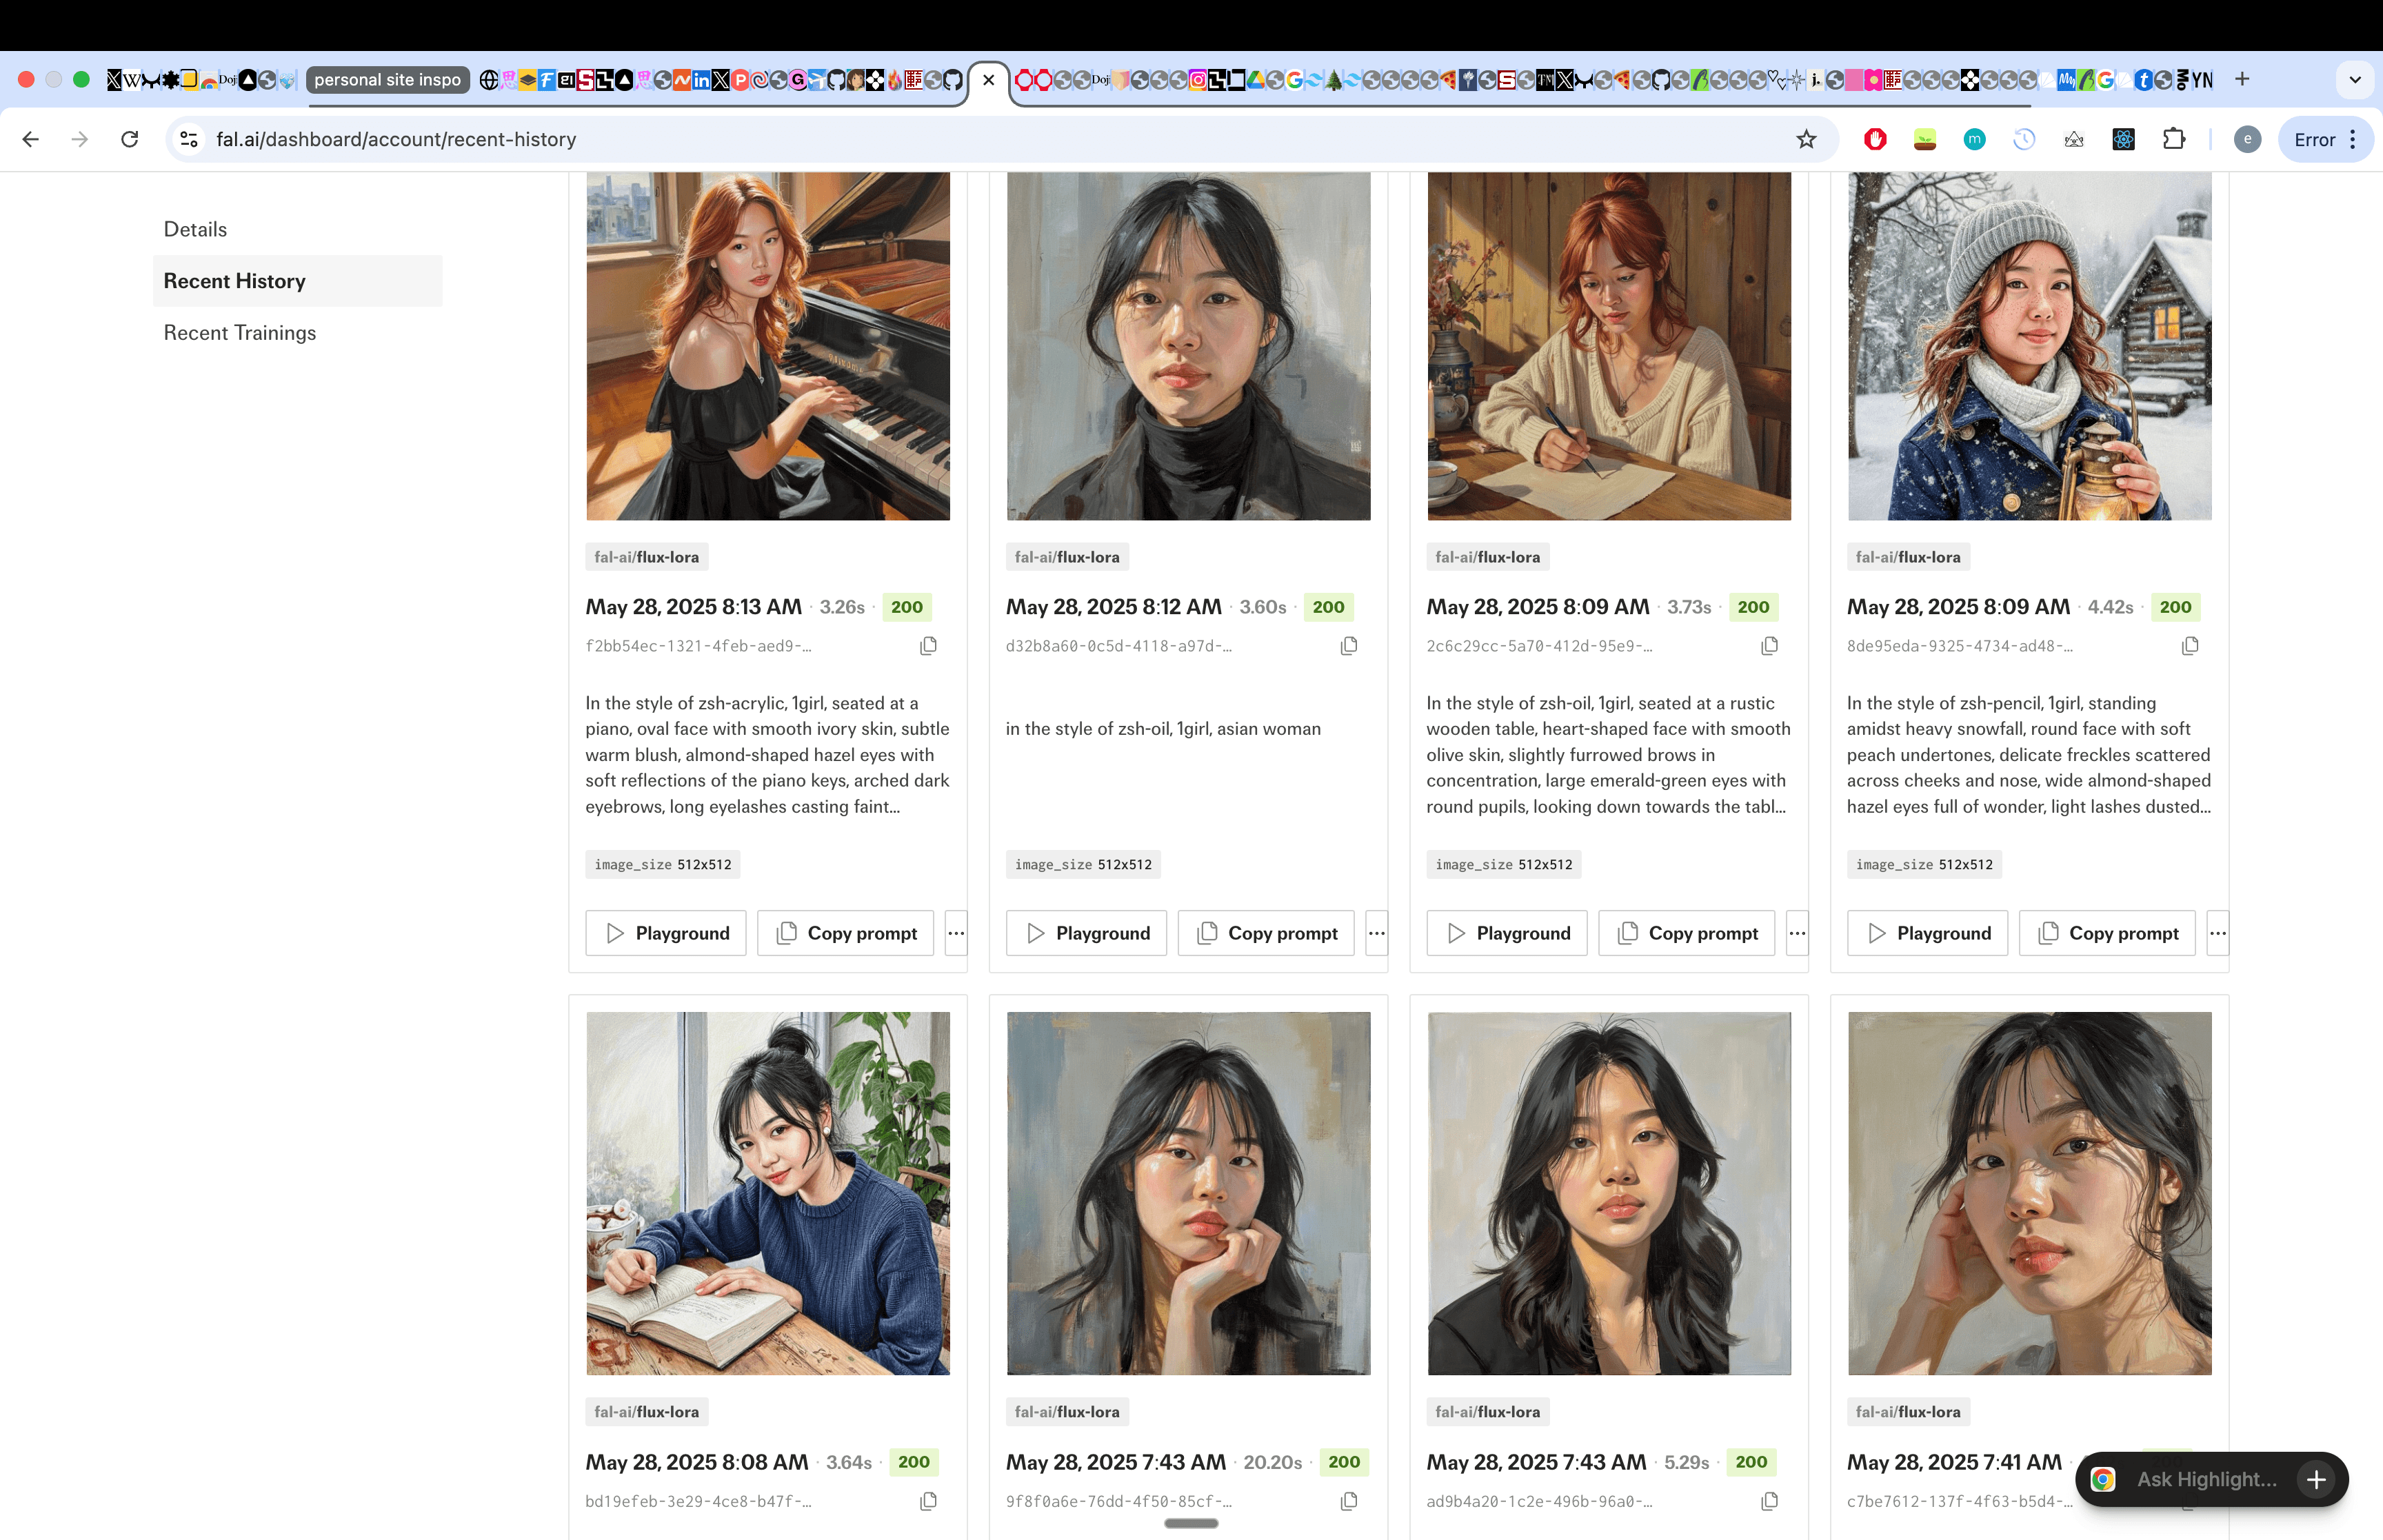
Notice the hair!!!
You can see how safely within distribution the LoRA stays in the following comparisons: (left is my original artwork, right is a generated sample).
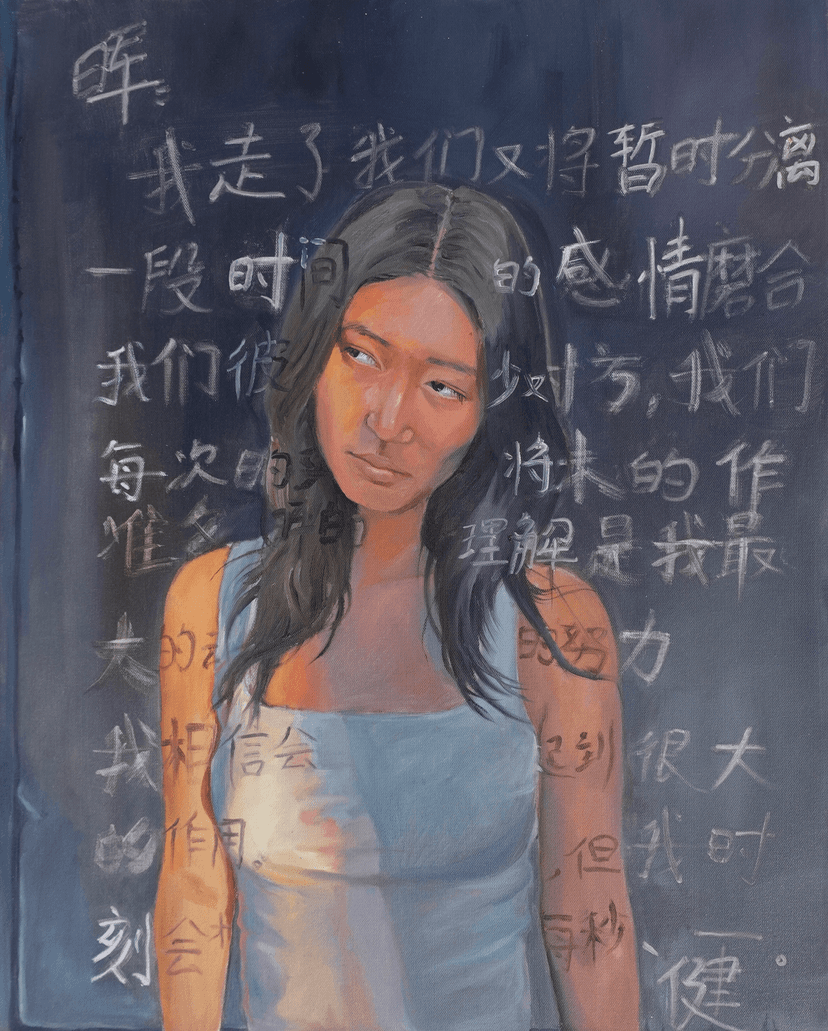
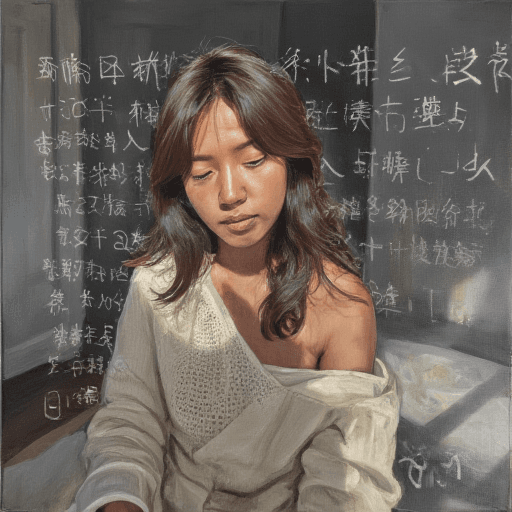
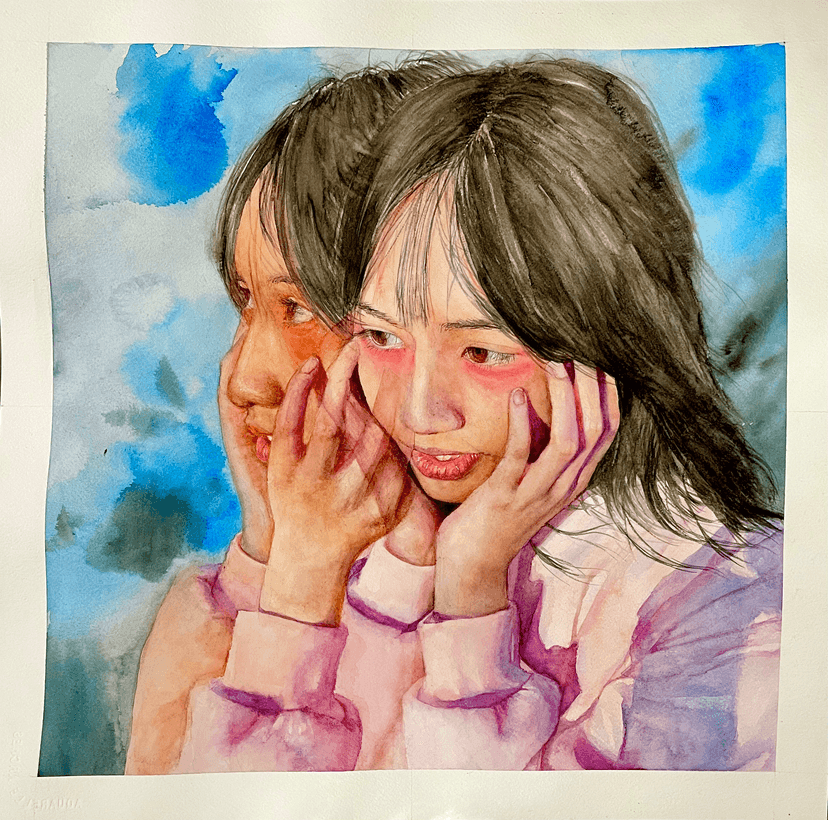
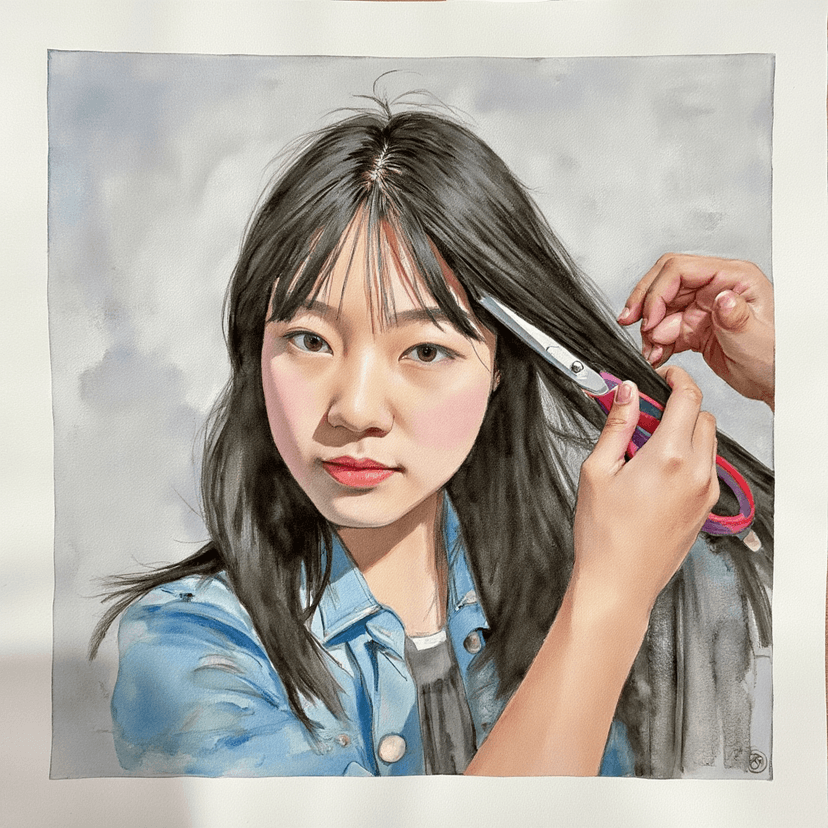
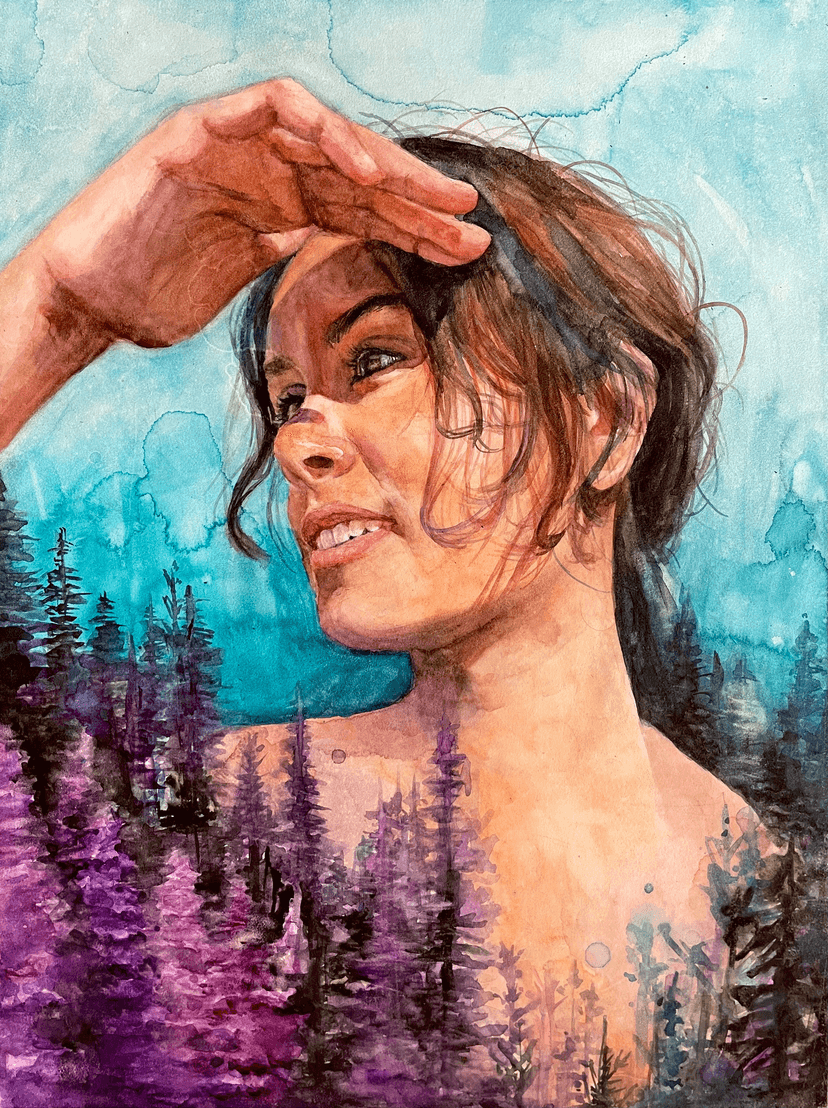
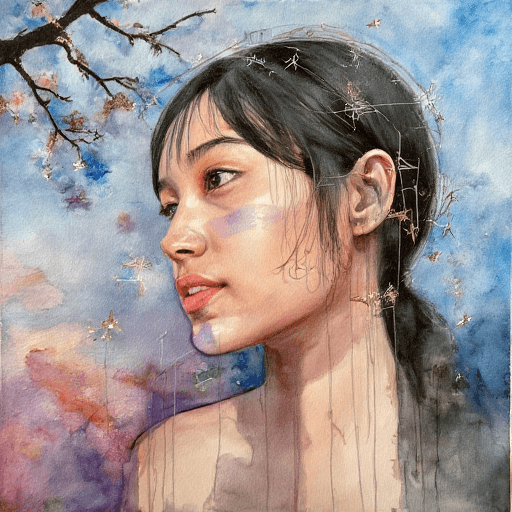
And, when you prompt for an image even slightly out of distribution, the generation either completely misses the style or has artifacts and bad quality. For example, most of my work is portraiture from the chest up. The model is the really bad at generating half/full-body poses and novel facial angles.